Activity 14.13.1.
Write down your best guess of what the code does.
#Get the webpage
# Load libraries for web scraping
from bs4 import BeautifulSoup
import requests
# Get a soup from a URL
url = 'https://www.si.umich.edu/people/barbara-ericson'
r = requests.get(url)
soup = BeautifulSoup(r.content, 'html.parser')

#Extract info from the webpage
# Get all tags of a certain type from the soup
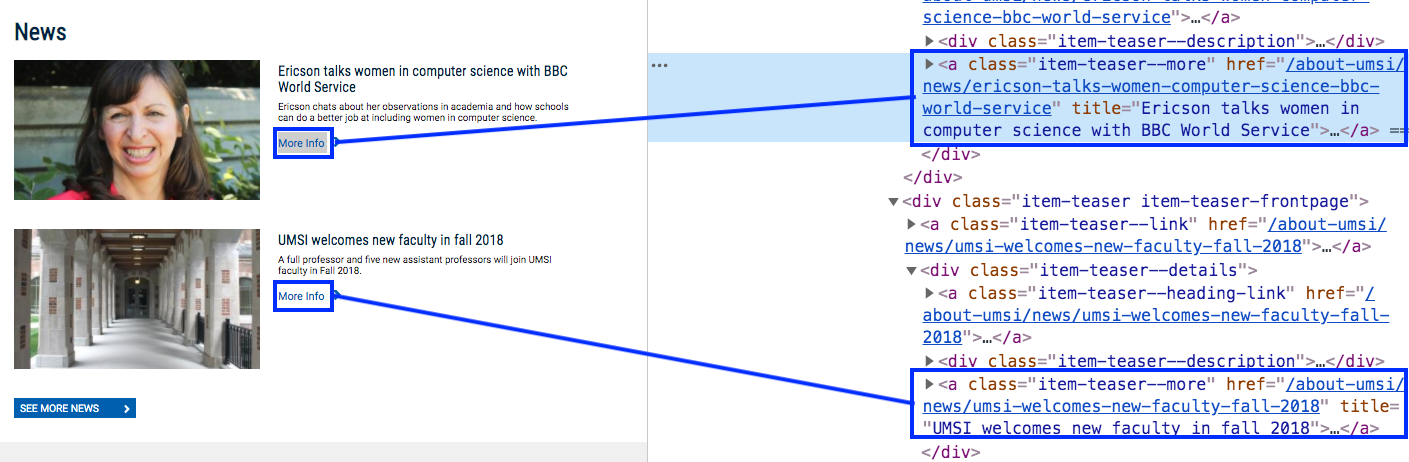
tags = soup.find_all('a', class_='item-teaser--heading-link')
# Collect info from the tags
collect_info = []
for tag in tags:
  # Get link from tag
  info = tag.get('href')
  collect_info.append(info)

#Do something with the info
# Get a soup from multiple URLs
base_url = 'https://www.si.umich.edu/'
endings = collect_info
for ending in endings:
    url = base_url + ending
    r = requests.get(url)
    soup = BeautifulSoup(r.content, 'html.parser')

    # Get all tags of a certain type from the soup
    tags = soup.find_all('p')
    # Collect info from the tags
    collect_info = []
    for tag in tags:
        # Get text from tag
        info = tag.text
        collect_info.append(info)

    # Print the info
    print(collect_info)

