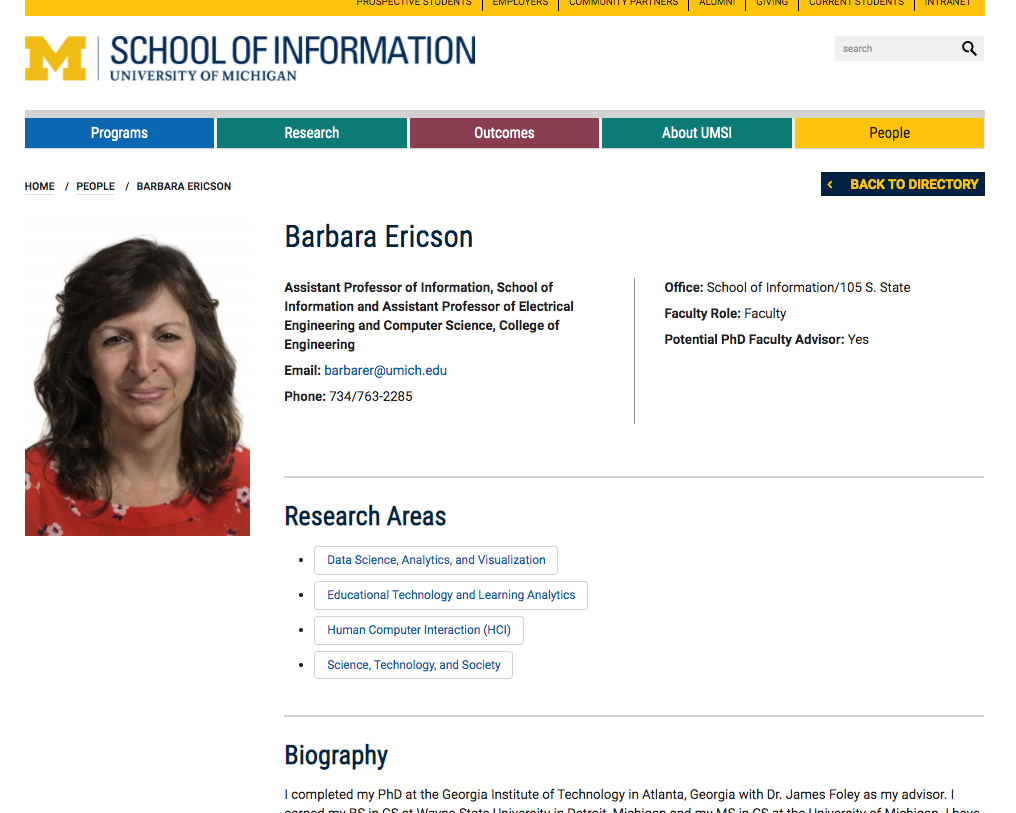
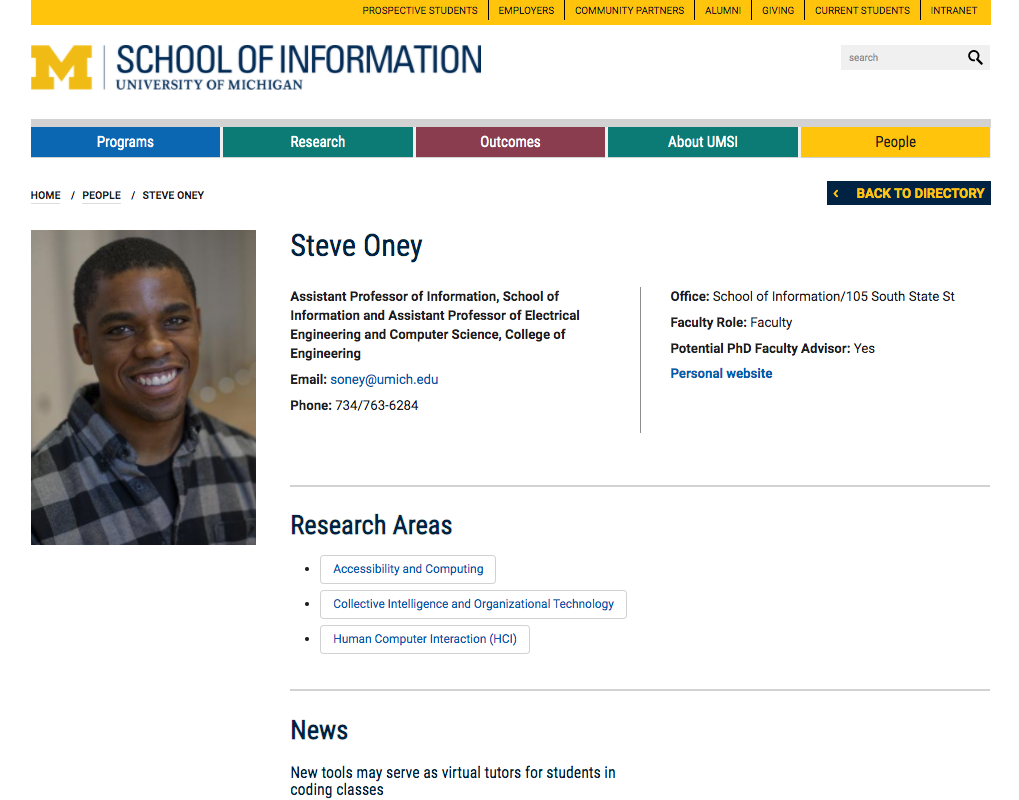
Sometimes we want to get information from multiple web pages that have the same layout. For example, all of the UMSI faculty pages have the same general design.
# Load libraries for web scraping
from bs4 import BeautifulSoup
import requests

# Get a soup from multiple URLs
base_url = 'https://web.archive.org/web/20230128074139/https://www.si.umich.edu/people/'
endings = ['barbara-ericson', 'steve-oney', 'paul-resnick']
for ending in endings:
    url = base_url + ending
    r = requests.get(url)
    soup = BeautifulSoup(r.content, 'html.parser')
Look at the urls for the webpages you want to scrape and determine which parts they have in common, and which parts are different. The parts that they have in common are the base_url. The parts that are different are the endings.
If you want to also get the link to the most recent news item from Dr Robin Brewer’s page, how would you change the code below? Her web page is https://web.archive.org/web/20230110174202/https://www.si.umich.edu/people/robin-brewer.