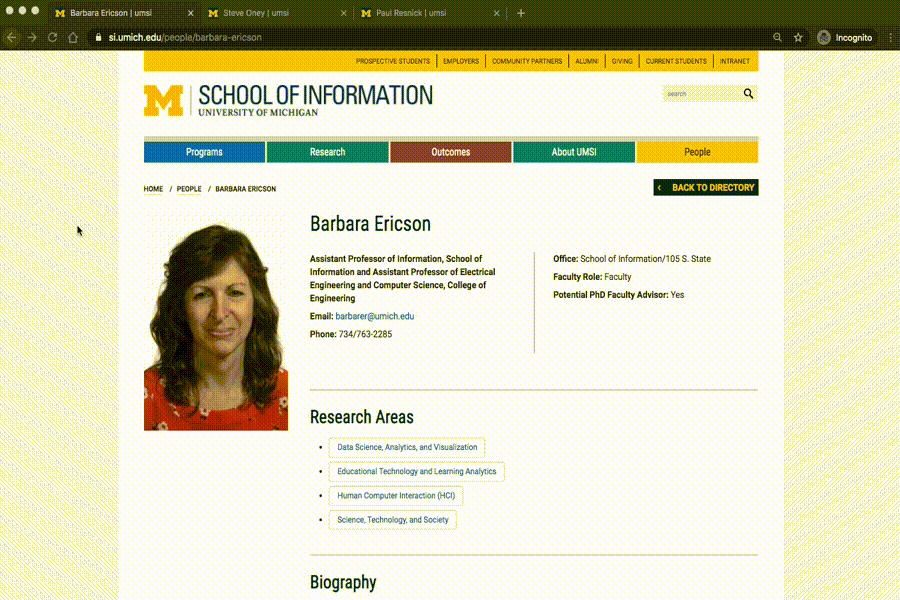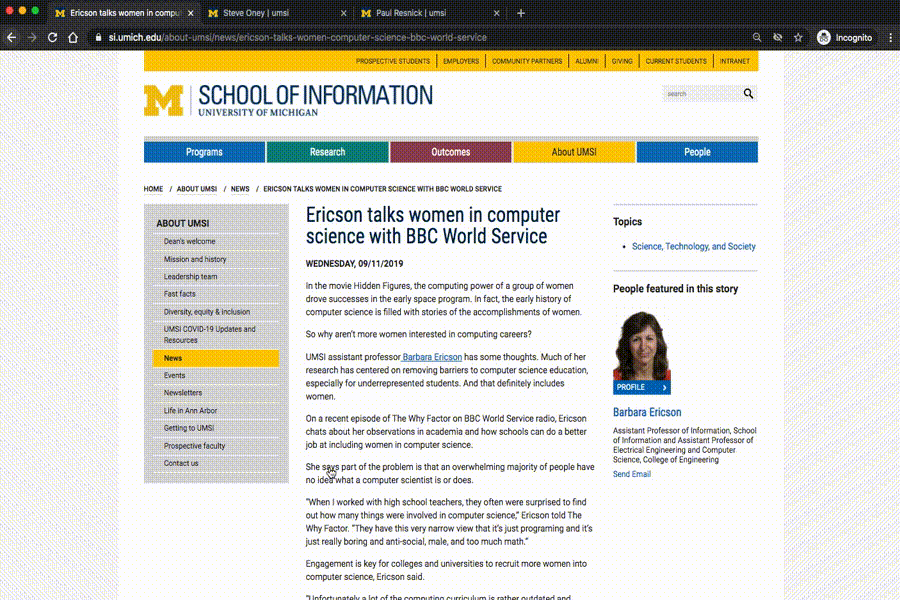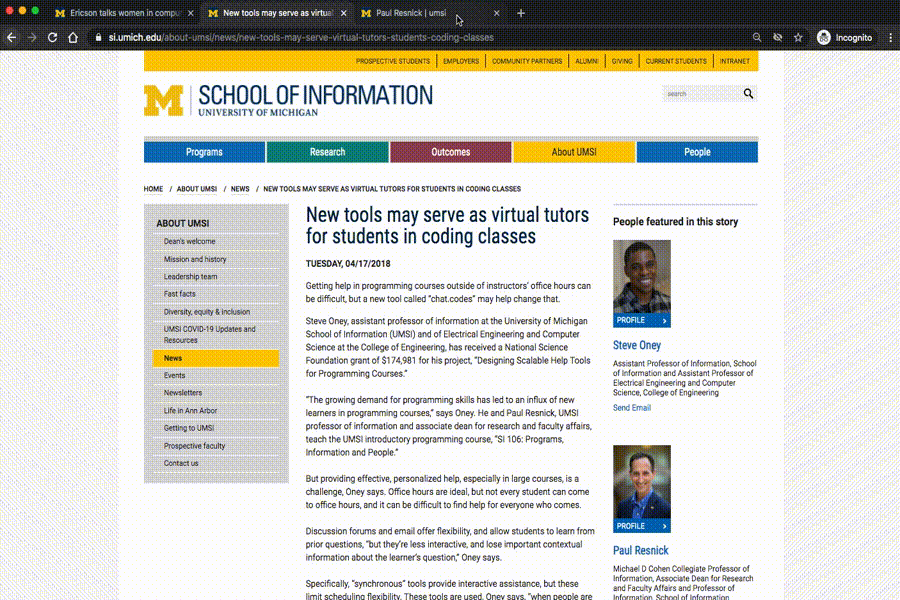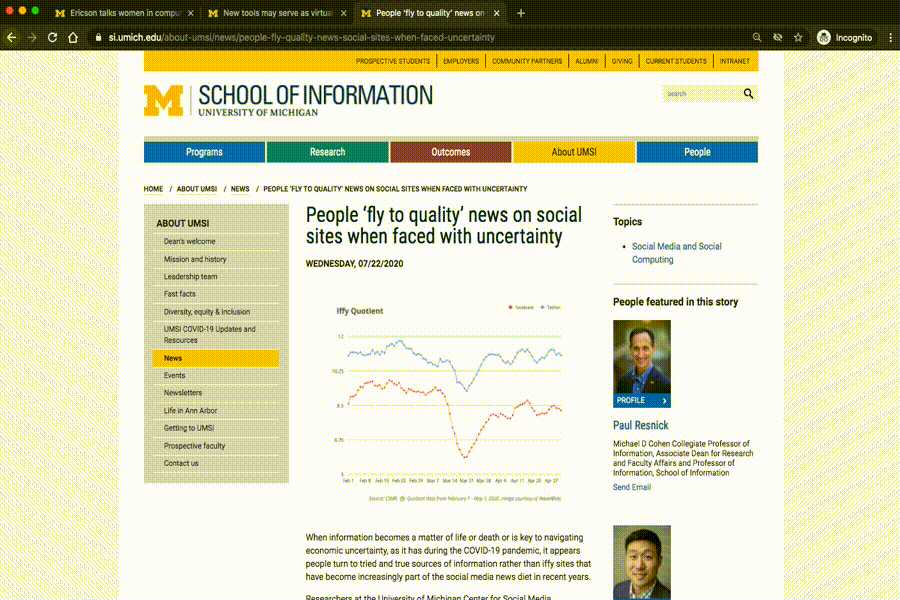
Activity 14.2.1. Run the code below to see what data it collects🔗 # Load libraries for web scraping from bs4 import BeautifulSoup import requests # Get a soup from multiple URLs base_url = 'https://web.archive.org/web/20230128074139/https://www.si.umich.edu/people/' endings = ['barbara-ericson', 'steve-oney', 'paul-resnick'] for ending in endings: url = base_url + ending r = requests.get(url) soup = BeautifulSoup(r.content, 'html.parser') # Extract info from the page # Get first tag of a certain type from the soup tag = soup.find('a', class_='item-teaser--heading-link') # Get link from tag info = tag.get('href') # Do something with the info # Print the info print(info) 🔗